Mohit Mendiratta

Head of AI Research at QOVES. Saarbrücken, Germany.

prof_pic.jpg

I lead the AI research team at QOVES, where we build facial analysis and AI-powered image editing products. My team of ML researchers and engineers works on taking 3D face models, generative editing and vision-language models from research into production.

My research sits at the intersection of computer vision and computer graphics, with a focus on photorealistic 3D faces and heads. I work on morphable models and Gaussian splatting head avatars, text-driven editing of dynamic 3D humans, and vision-language models that can reason about faces. Recent work includes GRMM, a real-time Gaussian morphable head model with learned residuals (3DV 2026), and AvatarStudio, text-driven editing of dynamic head avatars (SIGGRAPH Asia 2023).

I did my PhD research at the Max Planck Institute for Informatics in the Visual Computing and Artificial Intelligence department, advised by Christian Theobalt, from 2021 to 2026; the Dr.-Ing. defence is pending. Before that I completed an MSc in Visual Computing at Saarland University and a BTech in Electrical and Electronics Engineering at KIIT, Bhubaneswar. I review for SIGGRAPH, SIGGRAPH Asia, CVPR, 3DV and Eurographics.
Email    Google Scholar    GitHub    LinkedIn    CV (PDF)

selected publications

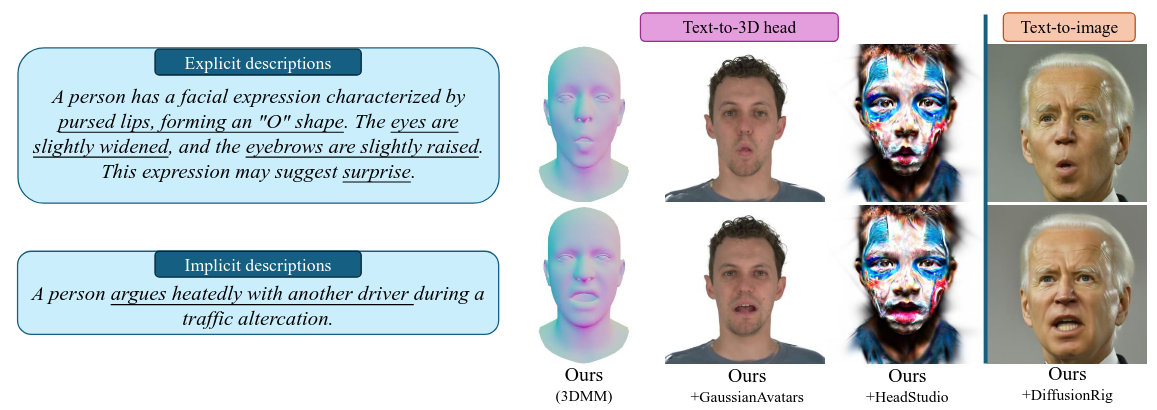
  1. EmoteGPT: 3D Human Facial Expressions from Natural Language Descriptions
    Haoran Wang, Mohit Mendiratta, Christian Theobalt, and Adam Kortylewski
    In European Conference on Computer Vision (ECCV), 2026
  2. 3DV
    GRMM.gif
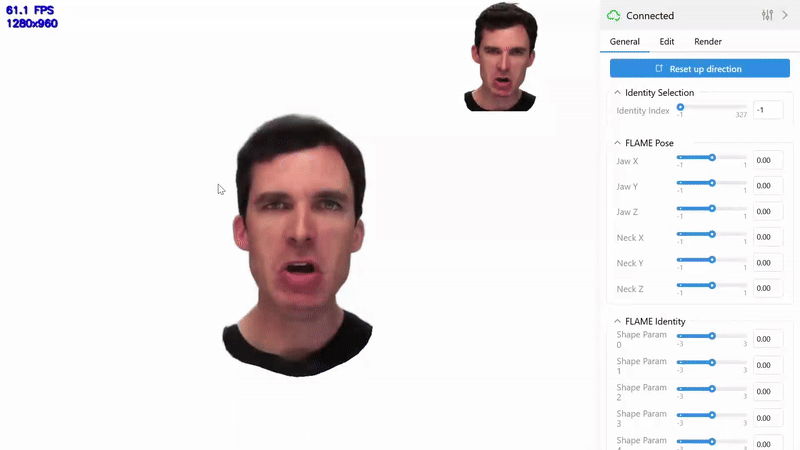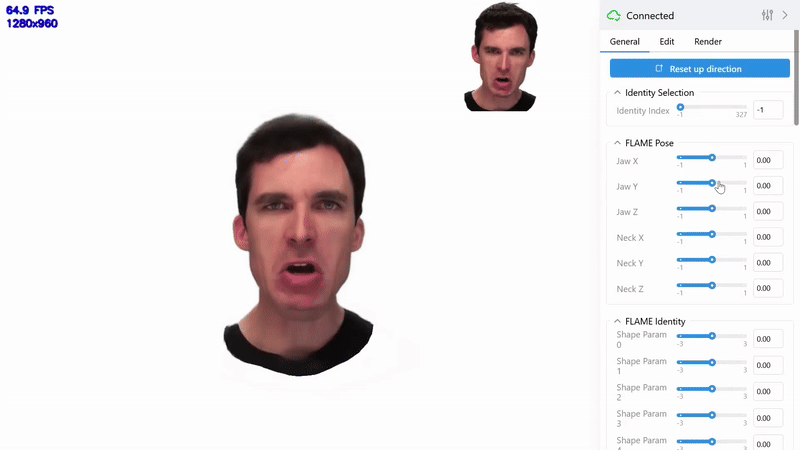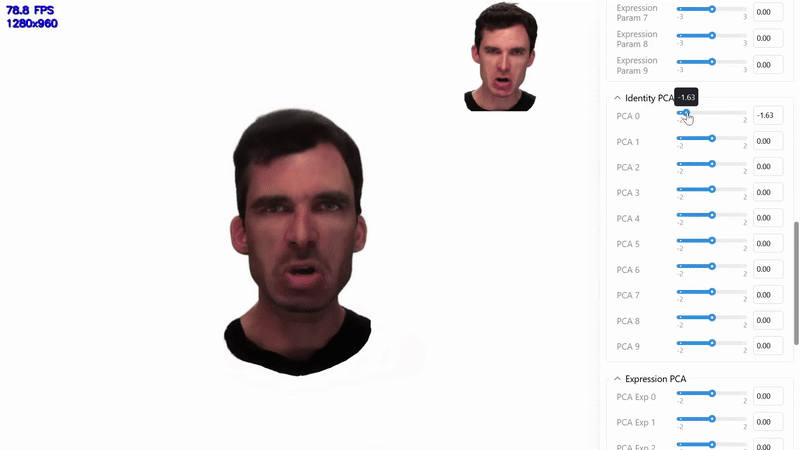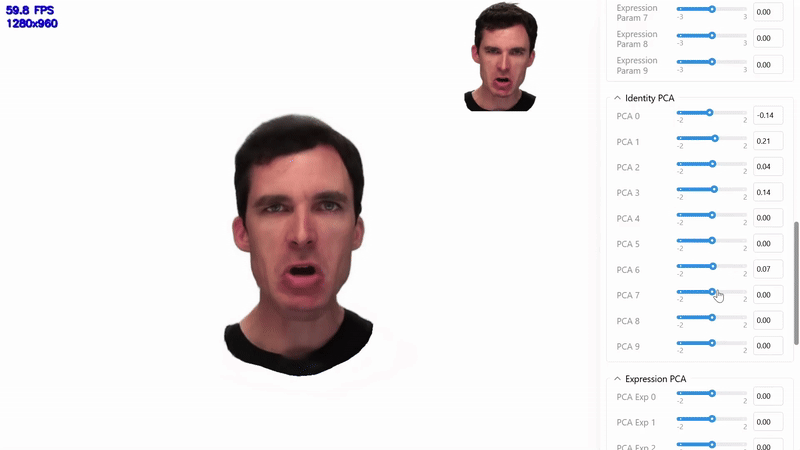
    GRMM: Real-Time High-Fidelity Gaussian Morphable Head Model with Learned Residuals
    Mohit Mendiratta, Mayur Deshmukh, Kartik Teotia, Vladislav Golyanik, Adam Kortylewski, and Christian Theobalt
    In International Conference on 3D Vision (3DV), 2026
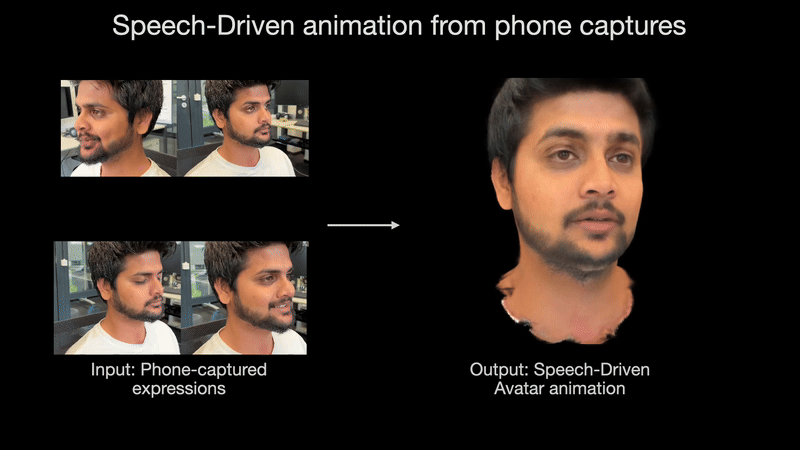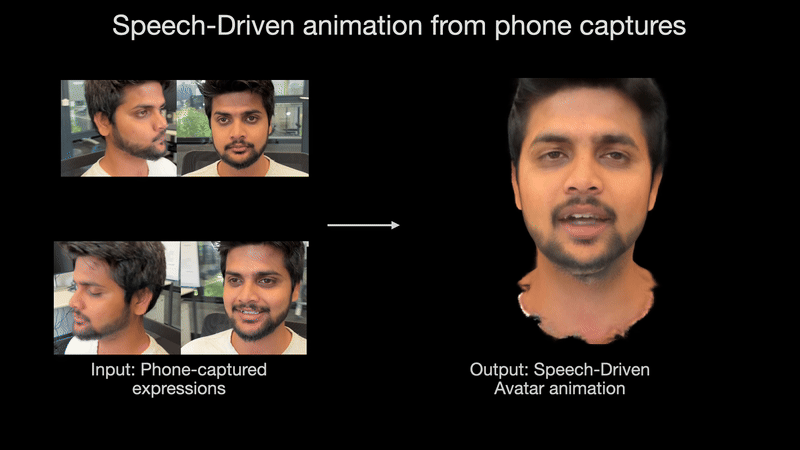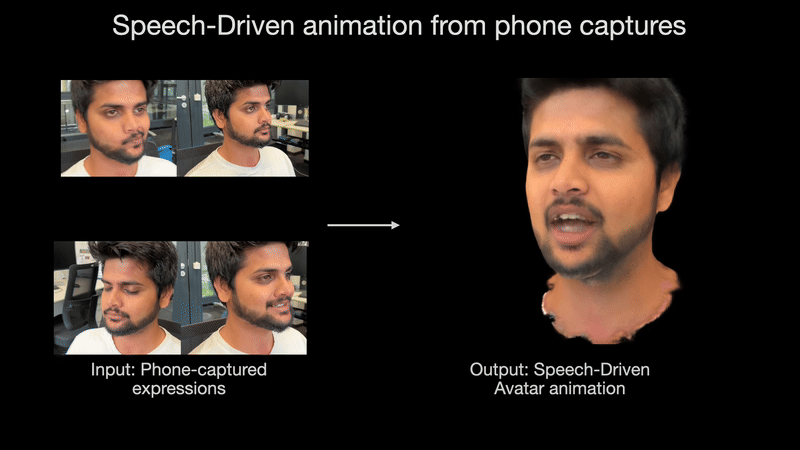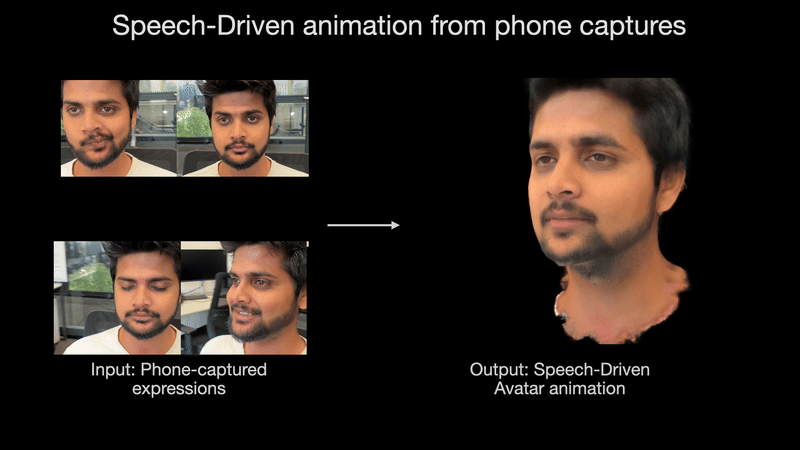
  3. Audio-Driven Universal Gaussian Head Avatars
    Kartik Teotia, Helge Rhodin, Mohit Mendiratta, Hyeongwoo Kim, Marc Habermann, and Christian Theobalt
    In SIGGRAPH Asia 2025 Conference Papers, 2025
  4. Zero-Shot Video Semantic Segmentation based on Pre-Trained Diffusion Models
    Qian Wang, Abdelrahman Eldesokey, Mohit Mendiratta, Fangneng Zhan, Adam Kortylewski, Christian Theobalt, and 1 more author
    In IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025
  5. 3DV
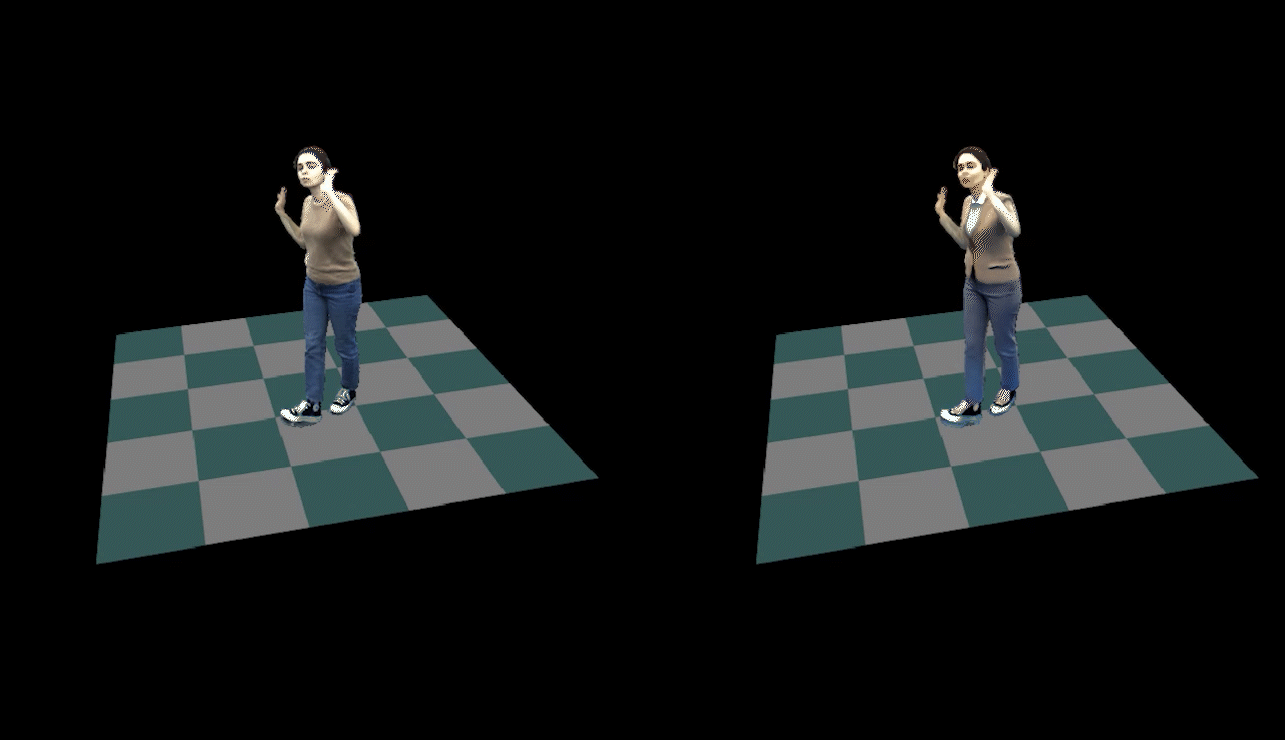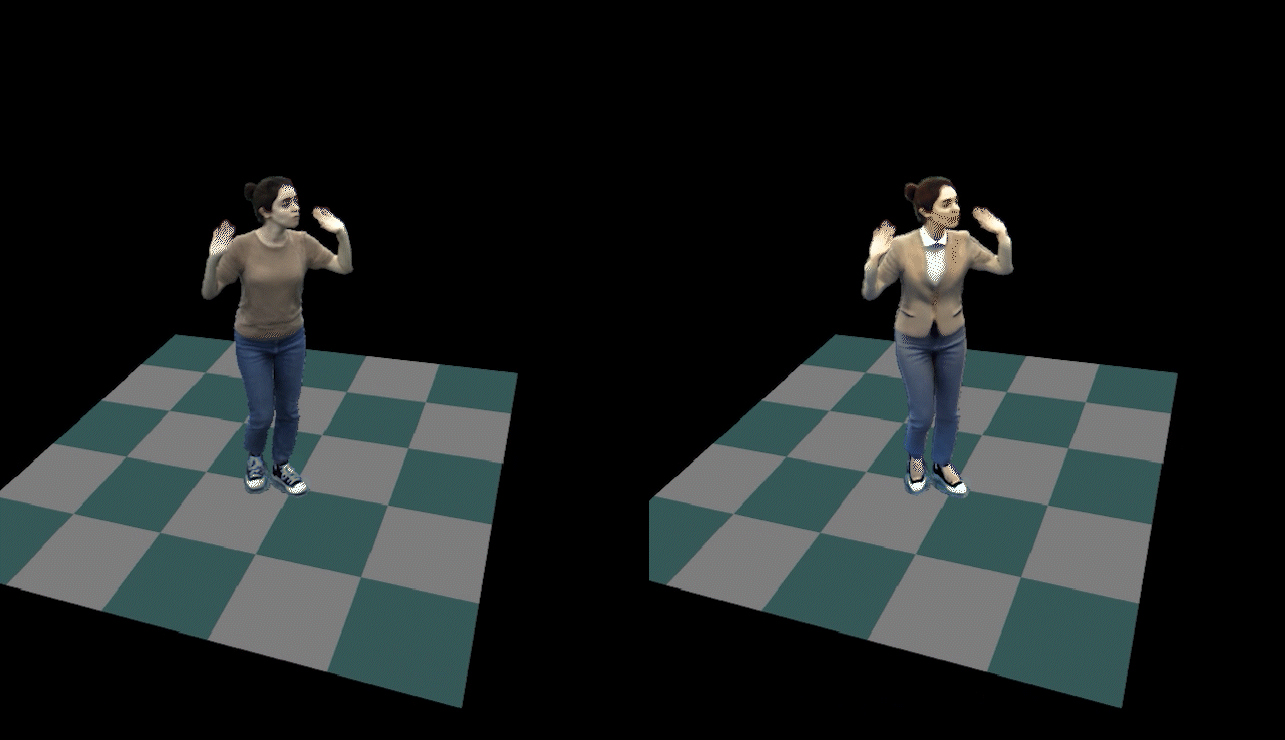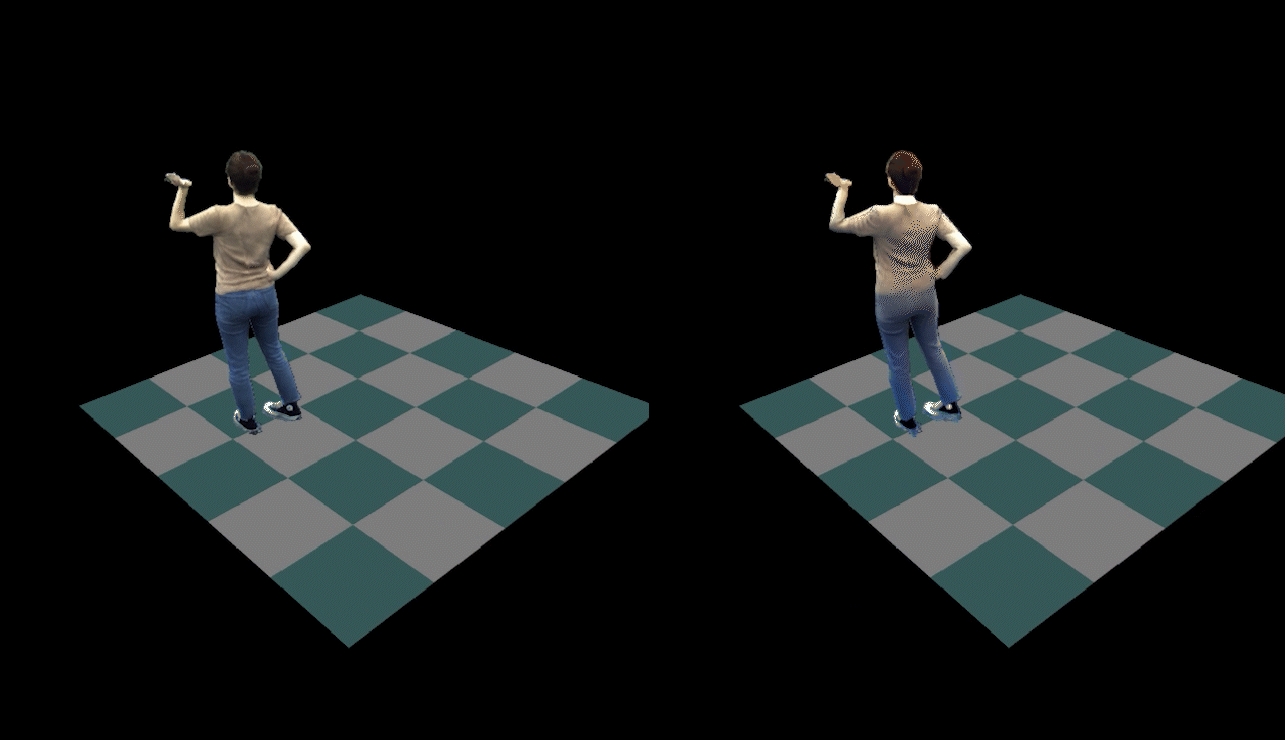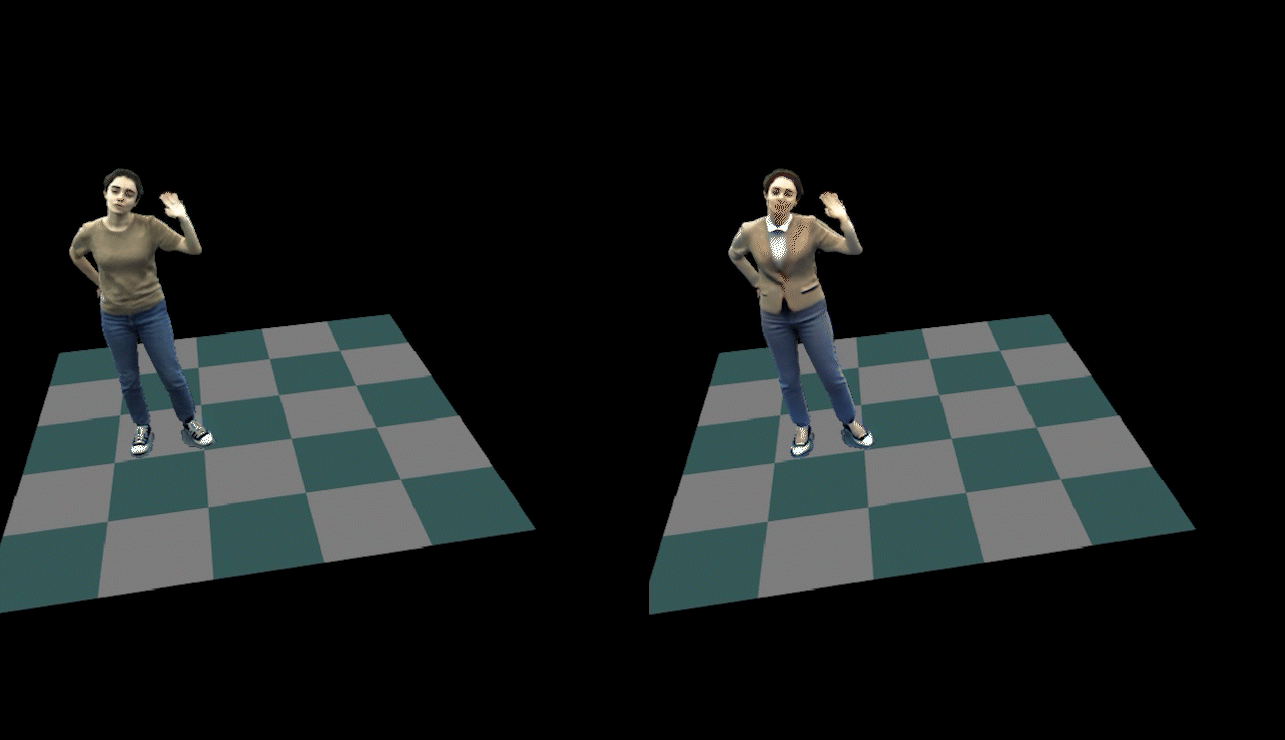
    tedra.gif
    TEDRA: Text-Based Editing of Dynamic and Photoreal Actors
    Basavaraj Sunagad, Heming Zhu*, Mohit Mendiratta*, Adam Kortylewski, Christian Theobalt, and Marc Habermann
    In International Conference on 3D Vision (3DV), 2025
  6. AvatarStudio: Text-driven Editing of 3D Dynamic Human Head Avatars
    Mohit Mendiratta, Xingang Pan*, Mohamed Elgharib*, Kartik Teotia, Mallikarjun B R, Ayush Tewari, and 3 more authors
    ACM Transactions on Graphics (Proc. SIGGRAPH Asia), 2023
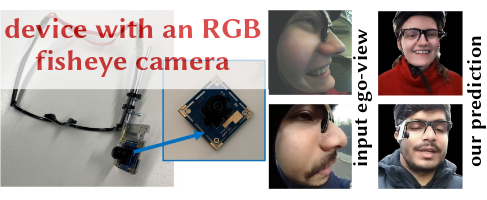
  7. Egocentric Videoconferencing
    ACM Transactions on Graphics (Proc. SIGGRAPH Asia), 2020

in the media

Two Minute Papers on Egocentric Videoconferencing (SIGGRAPH Asia 2020)
YouTube Short on Beauty is in the AI of the beholder (arXiv 2026)